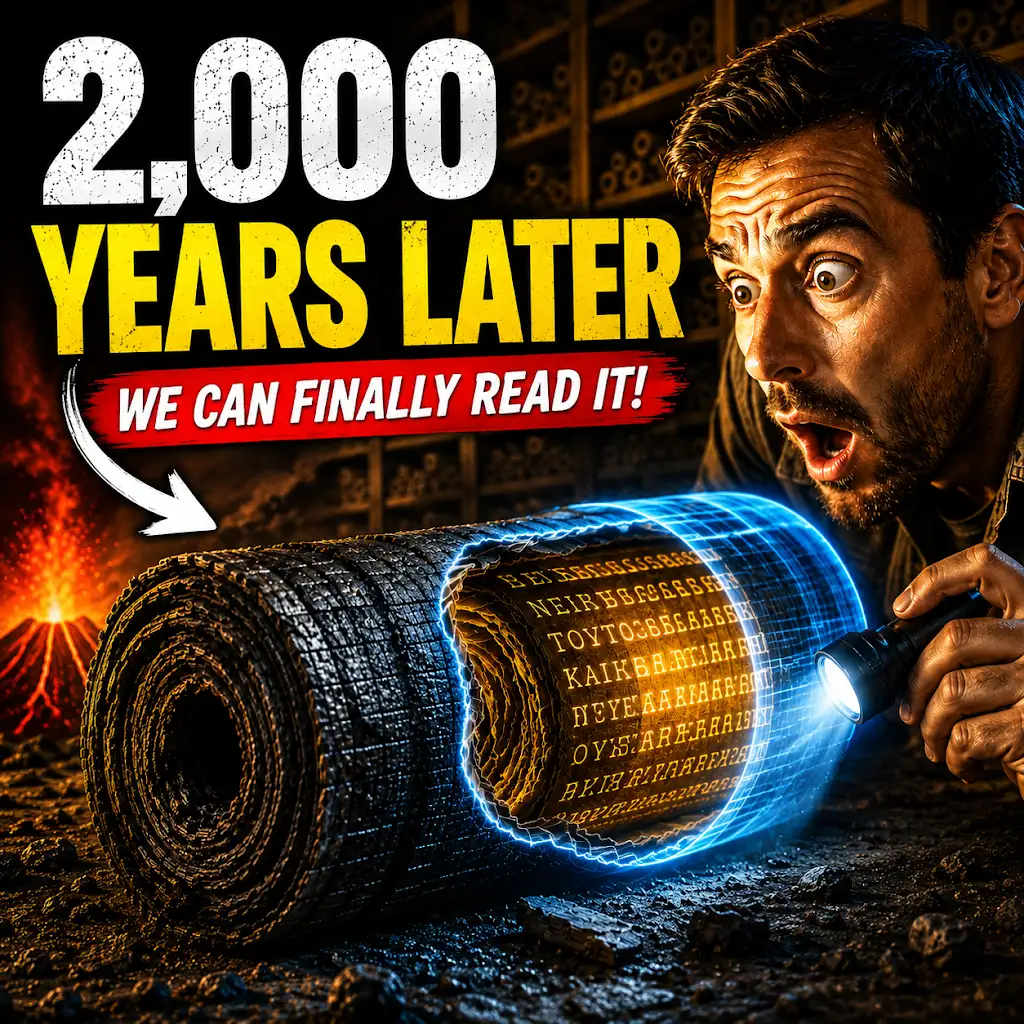
The allure of ancient texts, whether etched on stone, penned on papyrus, or inscribed on clay tablets, has captivated humanity for millennia. These fragile fragments of the past hold the keys to understanding forgotten civilizations, their beliefs, their scientific advancements, and their everyday lives. Yet, for many of these precious artifacts, the secrets they contain remain locked away, obscured by the ravages of time, the erosion of script, and the sheer volume of undeciphered languages. Now, a revolutionary frontier is emerging at the intersection of history and technology: machine learning is beginning to breathe new life into the deciphering of ancient scrolls, promising to unlock a treasure trove of lost knowledge. This burgeoning field, often referred to as “Machine Learning Ancient Scroll Decoding,” is not merely an academic pursuit; it is a powerful tool that can accelerate our understanding of human history on an unprecedented scale.
The challenge of decoding ancient texts is multifaceted. Languages evolve, scripts change, and the very materials upon which they were written degrade. Centuries of neglect, warfare, and natural disasters have left many scrolls damaged, fragmented, or incomplete. Traditional methods of decipherment, while often brilliant feats of linguistic and historical deduction, can be painstakingly slow, requiring years of dedicated scholarship for even a single text. This is where machine learning, with its ability to process vast datasets, identify complex patterns, and learn from experience, offers a paradigm shift. By training algorithms on known linguistic structures and identifying subtle visual cues within damaged texts, machine learning models can assist and even automate aspects of the decipherment process, revealing the whispers of antiquity that would otherwise remain silent.
The Scars of Time: Challenges in Ancient Textual Analysis
The physical state of ancient scrolls presents a formidable obstacle to their interpretation. Time, the ultimate destroyer, has left its indelible mark on these artifacts. Humidity, heat, light, and the simple act of handling have all contributed to the deterioration of fragile materials. Understanding these challenges is crucial to appreciating the impact of machine learning in this domain.
Material Degradation and Physical Damage
Papyrus, parchment, vellum, and even stone inscriptions are susceptible to various forms of decay. Papyrus can become brittle, prone to crumbling at the slightest touch. Ink can fade, bleed, or flake off. Parchment and vellum can become discolored, stiff, or infested with insects. Stone inscriptions can suffer from weathering, erosion, and deliberate defacement. These physical damages manifest as missing fragments, obscured characters, and blurred lines, making visual interpretation incredibly difficult.
Ink Fading and Bleeding
The chemical composition of ancient inks varied, and over time, these inks can undergo reactions that lead to fading or spreading, blurring the distinct outlines of characters. This makes it challenging to differentiate between individual strokes and to identify the precise shape of a letter.
Torn and Missing Sections
Many scrolls are not intact. They are often found in fragments, with significant portions missing due to historical events like fires, floods, or intentional destruction. Reconstructing these missing sections is a monumental task, relying heavily on contextual clues and educated guesses.
Surface Abrasion and Erosion
For inscriptions on harder materials like stone or pottery, weathering and abrasion can wear down the inscribed characters, making them less distinct or even entirely illegible. This is particularly problematic for texts intended to endure for centuries.
Linguistic Obscurity and Script Evolution
Beyond the physical challenges, the inherent nature of ancient languages and scripts poses significant hurdles. Languages disappear, their grammar and vocabulary forgotten. Scripts evolve, with characters taking on new forms or entirely new writing systems emerging.
Undeciphered Languages
The most significant linguistic challenge is the existence of entirely undeciphered languages, such as Linear A or the script of the Indus Valley Civilization. Without a Rosetta Stone or comparable bilingual text, these languages remain an enigma, and machine learning approaches are still in their nascent stages for tackling such completely unknown linguistic systems.
Variations in Script and Paleography
Even within a deciphered language, the form of a script can change dramatically over time. Paleographers, specialists in ancient handwriting, meticulously study these variations. Machine learning models can be trained to recognize these subtle shifts, aiding in dating texts and identifying scribal hands.
Semantic Drift and Archaic Vocabulary
The meaning of words can change over centuries. Vocabulary that was common in ancient times may be entirely unknown today. Machine learning can help identify recurring word patterns and suggest potential meanings based on statistical analysis and comparisons with known linguistic databases, though expert human oversight remains critical.
The Dawn of Algorithmic Decipherment: Machine Learning Approaches
The application of machine learning to ancient text decoding is not a single monolithic technique but rather a suite of diverse computational approaches, each tailored to address specific aspects of the problem. These methods leverage the power of algorithms to find patterns that might escape human observation.
Image Processing and Character Recognition
One of the most direct applications of machine learning involves enhancing and interpreting the visual information within images of ancient texts. This is particularly useful for damaged or faded inscriptions.
Optical Character Recognition (OCR) for Ancient Scripts
Traditional OCR technology, used for modern texts, is being adapted for ancient scripts. This involves training models to recognize individual characters, even when they are incomplete or distorted. This requires creating large datasets of annotated ancient characters.
Segmentation and Preprocessing
Before recognition can occur, the image of the text needs to be segmented into individual characters or even strokes. Preprocessing techniques like noise reduction, binarization, and contrast enhancement are crucial to improve the quality of the image for subsequent analysis.
Feature Extraction and Classification
Machine learning algorithms identify key features within each character, such as curves, straight lines, and loops. These features are then used to classify the character into a known letter or symbol from the target script. Deep learning models, such as Convolutional Neural Networks (CNNs), have proven particularly effective in this area.
Stylistic Analysis for Paleographic Dating
Beyond simple character recognition, machine learning can analyze the subtle stylistic variations in handwriting. This can help paleographers date texts more accurately, identify different scribes, and even potentially attribute texts to known individuals.
Stroke Analysis and Variability
By analyzing the thickness, curvature, and speed of strokes (where discernible), machine learning can identify individual scribal habits and patterns. This fine-grained analysis can reveal unique characteristics of a writer’s hand.
Letter Formation Patterns
Each scribe may have subtle variations in how they form letters. Machine learning models can learn these patterns and group texts with similar stylistic signatures, aiding in attribution and dating.
Natural Language Processing (NLP) for Linguistic Reconstruction
Once individual characters and words can be identified, Natural Language Processing (NLP) techniques come into play, leveraging statistical patterns in language to aid in understanding.
Statistical Language Modeling
Machine learning models can be trained on existing corpora of known ancient languages to learn the probability of character sequences, word combinations, and grammatical structures. This statistical understanding can help fill in missing words or suggest likely completions of fragmented sentences.
N-gram Analysis and Probability
This involves analyzing sequences of N characters or words. For example, a trigram model would analyze sequences of three characters. By understanding which sequences are common in a language, machine learning can predict missing elements.
Lexical Probability and Word Frequency
Understanding the frequency of words and their typical usage can help in deciphering new texts. Machine learning can build statistical models of vocabulary and word associations.
Machine Translation and Cross-Lingual Approaches
While direct machine translation of entirely unknown languages is still a distant goal, machine learning can facilitate translation efforts by assisting in identifying cognates and cognate shifts between related languages.
Leveraging Bilingual Corpora
When parallel texts exist (e.g., a known text translated into an unknown language), machine learning can be used to align segments and learn translation mappings, akin to how modern machine translation systems work.
Identifying Loanwords and Linguistic Influences
By comparing texts from different cultures and time periods, machine learning can help identify loanwords and linguistic influences, providing clues about linguistic relationships and historical interactions.
Training the Digital Scribe: Data and Model Development
The success of any machine learning endeavor hinges on the quality and quantity of data used for training. For ancient scroll decoding, this presents unique challenges and opportunities for innovation.
Curating and Annotating Datasets
The creation of comprehensive and accurate datasets is a foundational step. This involves digitizing existing manuscripts and meticulously annotating them.
Digitization Techniques and Standards
High-resolution imaging techniques, including multispectral and hyperspectral imaging, are employed to capture details invisible to the human eye, revealing faded ink or variations in material composition. Establishing consistent digitization standards is crucial for comparability.
Photogrammetry and 3D Reconstruction
For three-dimensional artifacts like pottery shards or stone tablets, photogrammetry can create detailed 3D models, allowing for virtual manipulation and analysis of inscriptions from different angles.
Multispectral and Hyperspectral Imaging
These advanced imaging techniques can reveal information about the chemical composition of inks and materials, helping to differentiate between written and unwritten surfaces or to highlight faded inscriptions.
Expert Annotation and Labeling
Human experts – epigraphers, paleographers, and linguists – play a vital role in labeling the digitized data. This includes identifying individual characters, words, and even semantic units. This manual annotation is time-consuming but essential for supervised learning.
Character-Level Labeling
Precisely delineating the boundaries of each character and assigning it the correct linguistic label is a fundamental task for training character recognition models.
Word and Sentence Segmentation
Identifying word boundaries and sentence structures in ancient texts, which often lack clear punctuation or spacing, is another crucial annotation task.
Algorithm Selection and Model Architectures
The choice of machine learning algorithms and their specific architectures is critical for optimal performance. The field is constantly evolving with new advancements.
Deep Learning Architectures (CNNs, RNNs, Transformers)
Convolutional Neural Networks (CNNs) excel at image recognition tasks, making them ideal for character identification. Recurrent Neural Networks (RNNs) and Transformer models are powerful for sequence processing and language modeling, aiding in word prediction and sentence reconstruction.
Convolutional Neural Networks (CNNs) for Image Analysis
CNNs are particularly adept at learning hierarchical features from images, allowing them to recognize patterns in the shapes and structures of ancient characters even when distorted.
Recurrent Neural Networks (RNNs) and LSTMs for Sequential Data
RNNs, and their more advanced variants like Long Short-Term Memory (LSTM) networks, are well-suited for processing sequential data like text. They can capture dependencies between characters and words in a sequence.
Transformer Models for Contextual Understanding
Transformer architectures, the backbone of modern NLP, can process entire sequences simultaneously and capture long-range dependencies, making them powerful for understanding sentence structure and meaning in ancient texts.
Transfer Learning and Few-Shot Learning
Given the often limited availability of annotated data for specific ancient languages, transfer learning (applying knowledge learned from one task to another) and few-shot learning (learning from very few examples) are becoming increasingly important.
Leveraging Pre-trained Models
Models pre-trained on large datasets of modern languages can be fine-tuned for ancient language tasks, significantly reducing the need for extensive training data from scratch.
Adapting Models to Scarce Data
Few-shot learning techniques enable models to learn new characters or linguistic patterns from just a handful of examples, making them applicable to less common or poorly preserved scripts.
Beyond Decipherment: Applications and Future Prospects
The impact of machine learning in ancient scroll decoding extends far beyond simply reading forgotten words. It opens up new avenues for historical research, cultural understanding, and even the preservation of human heritage.
Accelerating Scholarly Research and Discovery
The primary benefit is the dramatic acceleration of the decipherment process, allowing scholars to tackle larger volumes of texts and to uncover new information at a faster pace.
Cataloging and Indexing Vast Archives
Machine learning can assist in automatically cataloging and indexing vast digital archives of ancient texts, making them more searchable and accessible to researchers worldwide.
Automated Metadata Extraction
Algorithms can be trained to identify key metadata from images, such as the origin of a scroll, its approximate date, and its general subject matter, facilitating efficient organization.
Content-Based Indexing
Beyond basic metadata, machine learning can analyze the content of texts to identify thematic similarities, allowing for the creation of sophisticated, content-based indices that group related documents.
Identifying Patterns in Large-Scale Data
The ability of machine learning to process massive datasets allows for the identification of subtle patterns and connections that might be missed by individual scholars, leading to new insights into ancient societies.
Diachronic Linguistic Analysis
By analyzing large corpora of texts from different periods, machine learning can track linguistic evolution, changes in grammar, and the adoption of new vocabulary over time.
Social Network Analysis from Textual Clues
Inscriptions and texts can sometimes reveal social structures, relationships, and power dynamics. Machine learning can analyze these textual clues to reconstruct social networks.
Preserving Endangered Heritage and Digital Reconstruction
Machine learning plays a crucial role in preserving the fragile remnants of our past and even in digitally reconstructing lost texts.
Digital Restoration of Damaged Texts
Algorithms can be used to virtually “restore” damaged sections of scrolls, filling in missing characters or clarifying blurred text based on contextual information and learned patterns.
Inpainting Algorithms for Missing Fragments
Similar to digital art restoration, machine learning “inpainting” techniques can intelligently fill in missing sections of an image based on the surrounding content, creating a plausible reconstruction.
De-noising and Sharpening Algorithms
These algorithms can improve the clarity of faded or smudged inscriptions, making them more readable for both humans and other machine learning models.
Virtual Reconstruction of Lost Libraries and Archives
The ultimate goal could be to use machine learning to digitally reconstruct entire lost libraries or archives by analyzing fragments and inferring their original contents and organization.
Collaborative Reconstruction Efforts
Machine learning can act as a powerful collaborative tool, allowing researchers from different institutions and disciplines to contribute to the reconstruction of fragmented texts and collections.
Ethical Considerations and the Human Element
While the potential of machine learning in ancient scroll decoding is immense, it is imperative to acknowledge the ethical considerations and the indispensable role of human expertise.
The Risk of Algorithmic Bias and Misinterpretation
Machine learning models are trained on data, and if that data is biased, the model will reflect those biases, potentially leading to inaccurate interpretations or perpetuating historical misconceptions.
Data Representation and Fairness
Ensuring that the training data accurately represents the diversity of ancient scripts and languages is crucial to avoid algorithmic bias. This includes accounting for regional variations, scribal styles, and different social strata.
Bias in Annotation and Labeling
Human annotators can unconsciously introduce biases into the labeling process. Diverse teams of annotators and robust quality control measures are essential to mitigate this.
Over-reliance and the Loss of Critical Thinking
There is a risk that an over-reliance on automated decipherment could lead to a decline in critical thinking and the nuanced interpretative skills of human scholars.
The “Black Box” Problem
Understanding how a machine learning model arrives at its conclusions can be challenging. This “black box” nature can make it difficult to verify its reasoning and to identify potential errors.
The Indispensable Role of Human Expertise
Machine learning should be viewed as a powerful assistant, not a replacement, for human scholars. The unique insights, contextual understanding, and critical judgment of human experts remain paramount.
Complementary Strengths: Machine vs. Human
Machine learning excels at pattern recognition, data processing, and statistical analysis. Humans excel at contextual understanding, nuanced interpretation, creativity, and forming hypotheses.
The Scholar as the Final Arbiter
Ultimately, human scholars must review, validate, and interpret the results produced by machine learning models. Their expertise is crucial for drawing meaningful conclusions and avoiding misinterpretations.
The Future of Collaboration: Human-AI Synergy
The most promising future lies in the synergistic collaboration between human scholars and artificial intelligence. By combining the strengths of both, we can unlock the secrets of the past more effectively and efficiently than ever before. This partnership promises a richer and more comprehensive understanding of our shared human heritage.
In conclusion, the integration of machine learning into the ancient art of scroll decoding represents a transformative leap forward. By equipping historians, linguists, and archaeologists with powerful new tools, we are poised to uncover forgotten narratives, gain deeper insights into past civilizations, and enrich our understanding of the human journey. The echoes of antiquity, once fading, are now finding new voice through the intelligent algorithms of our modern age, promising a future where the wisdom of the past is not lost to us, but readily accessible and profoundly illuminating.